Key Takeaways
- Calibration requires a saved forecast, matching ground truth, and a clear definition of the wave height being scored.
- Calibration is the gap between what a global model predicts and what actually shows up at your beach. Closing that gap is the whole job.
- Forecast in, real buoy reading in, learn the gap, apply the correction next time. Repeat per beach. That's the whole loop.
- A forecast score needs a saved sample, named ground truth, reproducible rules, and clear limits.
- The calibration loop catches your own bugs. We fix them, retrain, and keep the old predictions honest instead of rewriting history.
The Short Answer
Calibration starts by saving a forecast before conditions arrive, then matching it to a later observation using a fixed station and time-window rule. For buoy checks, the ground truth is offshore significant wave height at the sensor. That is not the same quantity as breaking face height at the beach. Quiver documents this method and its limits at /forecast-accuracy; it does not publish an accuracy ranking against other forecasts.
What 'Calibrated' Actually Means
Most surf forecasts start in the same place: a global wave model run by NOAA or a similar agency. WaveWatch III, ECMWF, and Open-Meteo all produce hourly predictions of swell height, period, direction, and wind for every spot on the planet. Those models are good. They are not perfect.
The gap between "model output" and "what actually shows up at your beach" is what calibration closes. Two things drive that gap:
- Local seafloor and shoreline geometry. A global model has no idea your beach has a sandbar 300 feet offshore that turns a 4-foot reading into 3 feet of mush, or that the reef next door focuses the same swell into a head-high wall. The model just gives the open-ocean signal.
- Systematic model bias. Every model has tendencies. Some run hot on small swells. Some underestimate long-period north swells. Some are great on dominant swell but miss secondary windswell. These biases don't go away — they just need to be measured and corrected.
Calibration is the act of measuring those biases for your specific beach and correcting the next forecast accordingly. It's the difference between "this is what the model said" and "this is what the model said, adjusted for what we've observed at your beach over the last several months."
Calibration is the gap between what a global model predicts and what actually shows up at your beach. Closing that gap is the whole job.
How It Works for Your Beach
Here's the data flow, in plain English:
1. Save the forecast. Keep the raw model value and any adjusted value with the issue time, valid time, location, lead time, variable, and units.
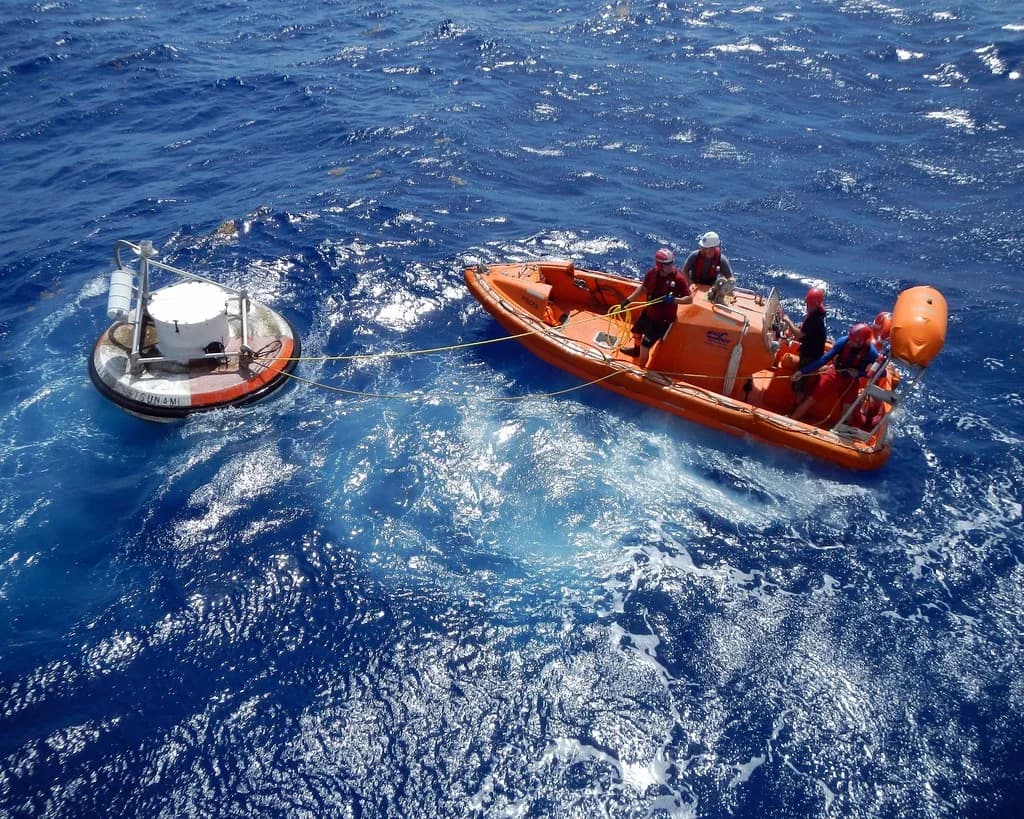
2. Pull the observation. Match the saved value to what a documented NDBC, CDIP, or IOOS buoy measured inside a fixed time window.
3. Keep the definition straight. A buoy reports offshore significant wave height. Do not label that as observed breaking face height at the beach.
4. Evaluate the adjustment. Compare the raw and adjusted offshore-height values on the same holdout sample. Keep the miss even when it is unfavorable.
5. Report the limits. Publish the sample, date range, beaches, forecast horizon, missing data, and error formula before making a performance claim.
This is not magic. It is a testable loop: predict, observe, measure, and keep the result. A correction only earns trust when the saved evaluation shows that it helped on unseen data.
How It Works for Your Beach
What the Method Has to Publish
Calibration only matters if it can be audited. The /forecast-accuracy page now states the standard Quiver expects its own evaluation to meet:
Preserve the forecast. The value must be saved before the observation arrives, with its timestamp, lead time, location, variable, and units.
Name the ground truth. Offshore significant wave height from a buoy and breaking face height at a beach are different quantities. A report must say which one it scores.
Use one sample for a comparison. Every provider must be evaluated across the same beaches, times, horizons, observations, and exclusion rules.
State what is missing. Quiver has not completed a same-sample comparison against other surf forecasts, so it does not claim an accuracy ranking.
A forecast score needs a saved sample, named ground truth, reproducible rules, and clear limits.
The Day I Caught My Own Bug
One thing about running a calibration loop is that it surfaces problems in your own code. You can't hide from it. The buoy is the buoy.
I shipped a forecast model, found a direction bug in our own data pipeline, fixed it, retrained it, and kept the old predictions instead of rewriting history. That's the difference: we check our own work.
The reason it matters is straightforward. If I'd quietly patched the model and replaced the old predictions, the evaluation would no longer describe what actually shipped. A forecast you can't audit isn't calibrated — it is just a number.
The model is a tool. The discipline is the loop: predict, observe, measure, and preserve the result. The method matters more than the marketing label.